Blogs Techno Insights

Delivering expertly crafted articles on technology, business, and digital innovation to empower your knowledge and drive success.

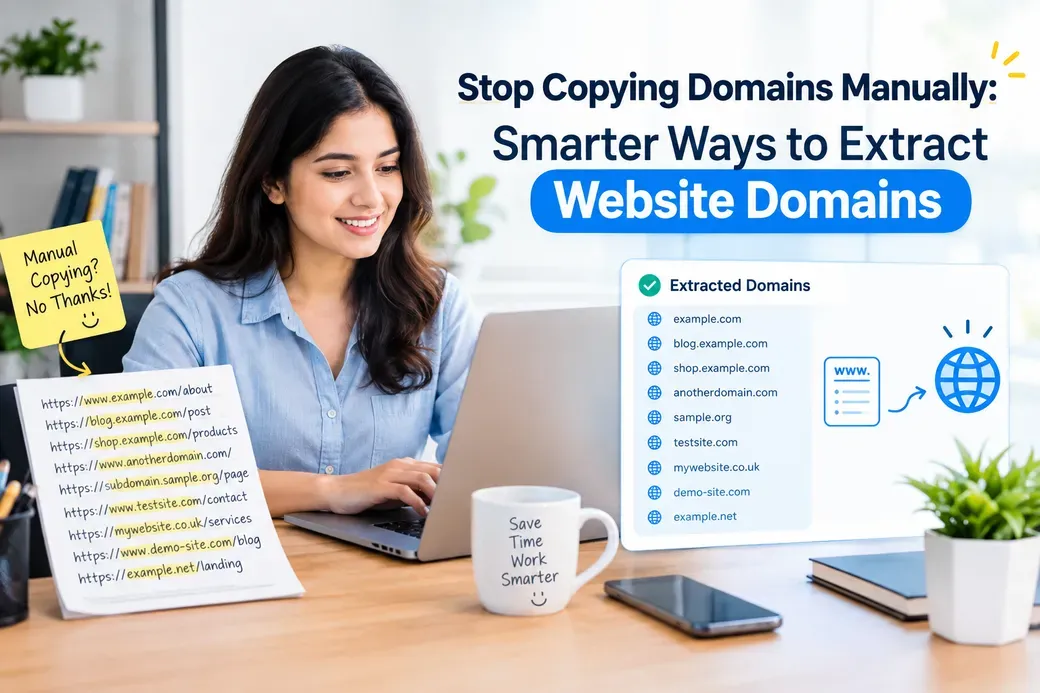
Stop Copying Domains Manually: Smarter Ways to Extract Website Domains

Working with long lists of websites can quickly become a tedious task when you need to identify and organize their domains one by one. A Domain Extractor can simplify this process by helping you pull clean domain names from website URLs without relying on repetitive manual work. Whether you are researching prospects, building a business database, or preparing data for outreach, automated domain extraction can make the workflow more organized and efficient. Why Manual Domain Copying Takes So Much Time A website URL contains more information than just its domain. It may include a protocol, subdomain, directories, tracking parameters, and page paths. For example: https://www.example.com/products/email-tools/?source=campaign The main domain is: example.com Finding this information manually across hundreds or thousands of URLs can take considerable time. It also increases the possibility of copying unnecessary parts of URLs or making formatting mistakes. A domain extraction tool can help separate the domain from the rest of the URL, giving you cleaner data to work with. What Is a Domain Extractor? A Domain Extractor is a tool designed to identify and collect domain names from URLs or website data. Instead of opening each website and copying its domain manually, you can process a list of URLs and organize the domains more efficiently. This can be useful when you need to: Build a prospect list Organize website research Clean URL datasets Identify company websites Prepare data for outreach Research businesses by their online presence Separate domains from long URLs The process is especially helpful when working with large datasets where manual copying becomes difficult to manage. How Domain Extraction Works The basic process is simple. 1. Collect Your URLs Start with a list of website URLs. These might come from a spreadsheet, research project, marketing campaign, or another source. 2. Process the URLs A domain extraction tool analyzes each URL and identifies the main domain portion. It can separate the domain from elements such as https://, page paths, and query parameters. 3. Create a Clean Domain List The extracted results can then be organized into a clean list. This makes the data easier to review, filter, and use in other marketing or research activities. 4. Use the Data for Research Once you have a structured domain list, you can use it for prospect research, company identification, lead generation, and other data-driven workflows. How Domain Extraction Supports Lead Generation Domain data can be useful when researching potential customers or businesses. For example, imagine you have a spreadsheet containing hundreds of company URLs. Instead of manually checking every URL, you can extract the domains and create a cleaner dataset. This can help you identify: Company websites Potential business prospects Websites within a particular industry Domains associated with existing leads Duplicate or repeated website entries Domain information can also be combined with other research methods to develop a more complete prospecting workflow. From Domains to Business Email Research A domain is often an important starting point when researching business contact information. Once you identify a company's website domain, you may want to look for relevant professional email addresses associated with that organization. If your goal is to Find Email Addresses from Any Website , understanding the relationship between websites, domains, and email addresses can make your research process easier to organize. For example, a company website might use a domain such as company.com , while its employees may have professional email addresses using the same domain. Domain information can therefore provide useful context during business research. Finding Business Email Addresses More Efficiently Lead generation often involves more than collecting company names and website URLs. Sales and marketing teams may also need professional contact information. The guide on Find Business Email Addresses for Free explores different approaches to finding business email information while researching potential contacts. A practical workflow can look like this: Collect company website URLs. Extract the relevant domains. Organize the domains into a clean list. Research publicly available business contact information. Verify and organize the information before using it. Keeping each step organized can make large-scale prospect research easier to manage. Combining Domain Extraction With Email Extraction Domain extraction and email extraction solve different parts of the same data research process. A domain extractor focuses on identifying website domains from URLs. Email extraction tools, on the other hand, focus on locating email addresses within suitable sources. If you are comparing different solutions, exploring the Best Email Extractor Tools 2026 can help you understand the types of tools available for email-focused data collection. Using the right tool for each stage can help prevent unnecessary manual work and keep your datasets structured. Why Understanding Email Basics Still Matters Automation is useful, but understanding the information you are working with is equally important. What Is Email explains the basic structure and purpose of email, which can help when working with email addresses and business contact data. A basic understanding of email also makes it easier to recognize how domains relate to professional email addresses. For example: alex@company.com Here, company.com is the domain portion of the email address. This connection between domains and email addresses is one reason domain extraction can be valuable during business research. Best Practices for Domain Extraction To keep your extracted data useful, follow a few simple practices: Start with clean URLs: Remove obvious duplicates before processing large lists. Check your results: Review extracted domains for unusual entries or formatting issues. Remove duplicates: The same domain may appear across multiple URLs. Keep original data: Save your source URLs so you can verify results later. Organize by purpose: Separate domains based on industry, campaign, location, or research goal when appropriate. Respect privacy and applicable laws: Use business data responsibly and follow relevant data-protection and outreach requirements. Final Thoughts Manually copying domains from large URL lists can be repetitive and difficult to maintain. A Domain Extractor provides a simpler way to turn messy website URLs into organized domain data. Whether you are performing website research, building prospect lists, or preparing information for business outreach, extracting domains can be a useful step in a broader data workflow. When combined with responsible email research and appropriate extraction tools, it can help create a more structured process from website discovery to useful business information. Frequently Asked Questions 1. What does a Domain Extractor do? A Domain Extractor identifies and separates domain names from website URLs. It helps turn long or complex URLs into cleaner domain-level data. 2. Why should I extract domains from URLs? Extracting domains can make website lists easier to organize, filter, research, and analyze. It can also be useful for lead generation and business prospect research. 3. Can I extract domains from multiple URLs? Yes. Domain extraction is particularly useful when you are working with a large collection of URLs and want to identify their domains without copying each one manually. 4. Are domains useful for finding business emails? Domains can provide useful context when researching professional email addresses because many businesses use their website domain as part of their email addresses. However, domain information alone does not guarantee that a particular email address exists. 5. Is domain extraction the same as email extraction? No. Domain extraction identifies website domains from URLs, while email extraction focuses on collecting email addresses from appropriate sources. The two processes can complement each other in a broader business research workflow.
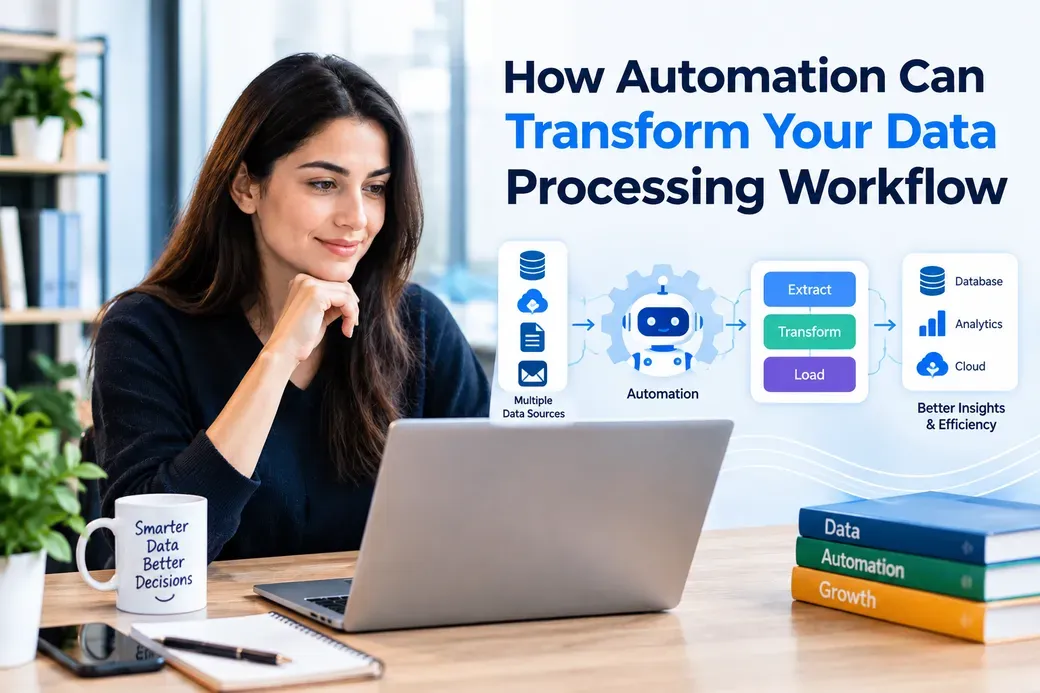
How Automation Can Transform Your Data Processing Workflow

Modern businesses handle data from many different sources. Customer records, emails, spreadsheets, CRM systems, websites, APIs, and business applications all generate information that teams need to collect and process. When this work is handled manually, employees may spend hours copying, cleaning, checking, and moving data between systems. This can slow down workflows and increase the chance of errors. Automation offers a more efficient approach. By combining structured processes with technologies such as ETL and workflow automation, businesses can move data through different stages with less repetitive manual work. One important part of this approach is ETL process optimization , which focuses on improving how data is extracted, transformed, and loaded into its final destination. What Is Data Processing Automation? Data processing automation means using software and predefined workflows to handle repetitive data-related tasks with limited manual intervention. A typical automated workflow may collect information from one or more sources, clean the data, apply specific rules, and send the processed information to another system. For example, a business may automatically: Collect customer information from different sources Remove duplicate records Standardize names and data formats Validate important fields Move processed information into a CRM Prepare data for reporting or analysis Instead of employees performing every step manually, automation allows systems to handle repeatable processes consistently. How ETL Supports Automated Data Workflows ETL stands for Extract, Transform, and Load. These three stages form the foundation of many data processing workflows. 1. Extract The first stage collects raw information from different sources. These sources may include: Databases CRM platforms APIs Spreadsheets Websites Business applications Email data The goal is to bring relevant information into the processing workflow. 2. Transform Raw data often needs to be cleaned and organized before it can be used effectively. During the transformation stage, a workflow may: Remove duplicate records Correct formatting issues Standardize values Validate information Filter unnecessary data Apply business rules This stage is important because poor-quality input can affect the systems and reports that depend on it. 3. Load After the data has been processed, it is moved to its destination. Depending on the business process, this could be a CRM, data warehouse, spreadsheet, marketing platform, or another business application. A well-designed ETL workflow makes this movement more structured and repeatable. Why ETL Process Optimization Matters Simply having an ETL workflow is not always enough. As data volumes increase, businesses also need to improve how those workflows operate. ETL process optimization can involve reviewing each stage of the pipeline and identifying unnecessary delays, repeated processing, data-quality problems, or inefficient transformations. For example, a business can look at: How quickly data is extracted How transformation rules are applied Whether duplicate information is being processed How often data is refreshed Whether the destination system can handle the incoming data Where errors or delays occur Optimizing these areas can help create a cleaner and more reliable data workflow. The Role of Automation in Reducing Repetitive Work One of the biggest advantages of automation is that it can reduce repetitive tasks. Imagine a sales employee receiving a spreadsheet containing hundreds of records. Manually checking each row, correcting formats, removing duplicates, and entering the information into a CRM could take considerable time. An automated workflow can perform many of these repeatable steps according to predefined rules. This does not mean that every part of data processing should be automated. Human review can still be useful when decisions require context, judgment, or business expertise. The goal is to automate predictable work while allowing employees to focus on tasks that require human input. How Robotic Process Automation Fits Into Data Processing Robotic Process Automation can also support repetitive digital tasks within business workflows. RPA generally uses software bots to perform rule-based actions that a person would otherwise complete through a computer interface. For example, an RPA workflow could potentially: Move information between business applications Copy structured data between systems Trigger predefined actions Process repetitive form-based tasks Collect information from supported interfaces Update records based on established rules RPA and ETL can serve different purposes, but they can also complement each other. ETL is commonly associated with extracting, transforming, and loading data, while RPA can help automate repetitive interactions across applications. The right approach depends on the type of process, data source, and business requirement. Building a Smarter Automated Data Workflow A successful automation process starts with a clear workflow rather than simply adding more tools. Step 1: Identify Repetitive Tasks Start by finding tasks that employees perform repeatedly. Look for processes involving frequent copying, formatting, validation, data entry, or movement between systems. Step 2: Identify Your Data Sources Document where the information comes from. For example, your workflow may receive data from CRM systems, spreadsheets, emails, websites, or APIs. Understanding the sources helps determine how the extraction stage should work. Step 3: Define Data Rules Before automating the transformation stage, establish clear rules. Decide how your system should handle: Duplicate records Missing information Incorrect formats Invalid values Different naming conventions Clear rules make automated processing more predictable. Step 4: Choose the Destination Determine where the processed information needs to go. It could be a CRM, data warehouse, spreadsheet, reporting system, or another application. Step 5: Monitor the Workflow Automation should not mean “set it and forget it.” Regular monitoring can help identify failed processes, unexpected data changes, duplicate records, and performance issues. Common Challenges With Data Processing Automation Automation can improve repetitive workflows, but it also requires planning. Poor Data Quality Automation cannot automatically make bad input useful. If source data is incomplete or inaccurate, those problems may continue through the workflow unless validation and cleaning steps are included. Changing Data Sources APIs, applications, and databases can change their structure over time. A workflow that depends on a specific field or format may need updates when its source changes. Complex Transformations Some businesses have complicated rules for combining, filtering, calculating, or categorizing data. These processes may require more detailed workflow design. Scalability A workflow that works well with a small dataset may need adjustments when the volume grows. Processing speed, storage, and system capacity should be considered during planning. Best Practices for Better Data Automation A few practical habits can make automated workflows easier to manage. Start with a clear process: Document the existing workflow before automating it. Validate important data: Add checks for missing, duplicate, or incorrectly formatted information. Keep workflows simple: Avoid unnecessary steps that make maintenance harder. Monitor performance: Track errors, processing time, and data quality. Review automation regularly: Update workflows when business requirements or data sources change. Protect sensitive information: Apply appropriate access controls and security practices. Keep human oversight where needed: Not every decision should be automated. From Manual Processing to Smarter Workflows Automation is not simply about replacing manual work. It is about creating a more organized way to move information through a business. A well-designed workflow can connect data sources, transformation rules, validation steps, and destination systems into a repeatable process. When combined with ETL process optimization , automation can help businesses identify inefficient steps and create more structured data pipelines. RPA can also support repetitive application-based tasks where appropriate. The most effective approach depends on the business process, the type of data being handled, and the systems involved. Starting with a clear workflow and improving it over time can make automation easier to manage and scale. Frequently Asked Questions 1. What is data processing automation? Data processing automation uses software and predefined rules to collect, organize, transform, validate, and move information with less manual intervention. 2. How does ETL process optimization improve data workflows? ETL process optimization focuses on improving the extraction, transformation, and loading stages. It can help identify inefficient steps, data-quality problems, processing delays, and unnecessary work within a data pipeline. 3. Is Robotic Process Automation the same as ETL? No. ETL focuses on extracting, transforming, and loading data, while Robotic Process Automation is generally used to automate repetitive, rule-based tasks across software applications. They can sometimes be used together. 4. Can small businesses use automated data processing? Yes. Small businesses can automate repetitive processes when there is a clear business need. Starting with one time-consuming workflow can be a practical way to introduce automation without redesigning every process at once. 5. What should businesses consider before automating a data workflow? Businesses should consider the data sources, processing rules, data quality, destination systems, security requirements, scalability, monitoring needs, and the amount of human oversight required.